GroupWise Mobility Service (GMS) Best Practice Guide
This guide provides practical guidance for installing, configuring, upgrading, and maintaining GroupWise Mobility Service environments. It is based on long-term, real-world experience supporting GroupWise and GMS deployments across a wide range of production environments. The intent is to supplement official documentation with operational insight and field-tested practices that are often not captured in vendor guides.
For some deeper discussions on earlier versions reference the legacy document that I have published here: https://www.redjuju.com/technical-resources/groupwise-mobility-service-gms-best-practice-legacy/
Preface
GroupWise Mobility Service has undergone significant architectural changes over the years, particularly involving Python, Django, and operating system dependencies. Two important considerations remain:
- User Provisioning and Authentication: Users are provisioned individually or through GroupWise Groups. LDAP-based provisioning and authentication are no longer supported.
- Upgrades: In-place upgrades are generally supported for GMS 18.3.1 and later. However, the older the installation, the more challenging a successful upgrade may become, particularly when significant operating system and software dependency changes are involved.
For version-specific changes and compatibility requirements, refer to the GroupWise Mobility Service Release Notes.
Updating and Patching GroupWise Mobility Service
Over the years, I've encountered numerous problems when applying updates to GroupWise Mobility Service (GMS), particularly when dealing with older installations, operating system updates, and software dependencies. Fortunately, the update process has become considerably more reliable with newer releases.
There are three types of updates that administrators need to consider:
- Routine SLES updates from the SUSE update channels.
- GroupWise Mobility Service software upgrades.
- Major SLES service pack upgrades.
Each can be performed independently, but when multiple updates are required, I recommend following a specific order.
Recommended Upgrade Order: Best Practices
The following recommendations assume the server is running SLES 15 SP4 or later. Earlier SLES versions are outside the scope of this guide.
Based on my experience upgrading and maintaining GroupWise Mobility environments, I recommend the following sequence:
- Apply SLES Channel Updates First: Install all available maintenance patches from the SUSE update channels, regardless of the current SLES service pack.
- Upgrade GroupWise Mobility: Update GMS to the latest supported release compatible with the current operating system.
- Upgrade the SLES Service Pack: If the server is not already running SLES 15 SP7 (the latest service pack as of this writing), perform the service pack upgrade after updating GMS, following the supported SUSE migration path.
Important: Perform each operation separately, with a VM snapshot or reliable backup beforehand. Verify that GMS is functioning correctly before proceeding to the next step. Also confirm that the selected GMS release supports both the existing and intended SLES versions.
1. Applying SLES Channel Updates
Routine SLES updates are an important part of maintaining a secure and stable GMS server. These updates are delivered through the SUSE update channels and should be applied regularly.
I strongly recommend scheduling a maintenance window and stopping GMS services before applying updates. Although it is possible to patch SLES while GMS is running, changes to underlying libraries and system components can interrupt synchronization even when the services themselves appear to remain active.
Check for available patches:
zypper patch-checkApply the available patches:
zypper patch
For routine SLES maintenance, I recommend zypper patch rather than zypper up. The patch command applies applicable maintenance patches from the configured repositories, while up performs broader package updates.
After installing the updates, reboot the server and verify that GMS is functioning correctly.
I generally do not recommend configuring unattended SLES updates on a production GMS server. I prefer to control when updates are applied and confirm that synchronization is working afterward.
2. Upgrading GroupWise Mobility Service
In-place upgrades are generally supported for GMS 18.3.1 and later. However, the older the installation, the more challenging an upgrade may become, particularly when significant operating system and software dependency changes are involved.
Before upgrading, verify that the installed SLES version is supported by the target GMS release. I also recommend applying all available SLES channel patches before upgrading GMS.
The upgrade process uses the full GroupWise Mobility installation media.
Upgrade Procedure
- Download the appropriate GroupWise Mobility Service ISO.
- Copy the ISO to the GMS server.
- Mount the ISO to the Linux filesystem.
- Run the installer and follow the prompts.
- Allow the installer to stop and update the existing GMS installation.
- Verify functionality after the upgrade completes.
For example, assuming the ISO is in your current directory:
mount -o loop groupwise-mobility-service-xx.x-x86-64.iso /mnt
cd /mnt
./install.sh
The installer will detect the existing installation and guide you through the upgrade process. In most cases, the process is straightforward and does not require extensive intervention.
Pay attention to any prompts regarding existing configuration settings, logging levels, or other options. Unless there is a specific reason to change them, I generally prefer to retain existing settings.
After the upgrade, confirm that GMS services are running and synchronization is functioning normally.
3. Upgrading the SLES Service Pack
Major SLES service pack upgrades introduce more significant operating system changes than routine channel updates. These upgrades should be planned carefully, particularly when working with older GMS installations.
My preferred method is to use the SUSE online migration utility.
Before performing a service pack upgrade:
- Apply all available SLES channel patches.
- Upgrade GMS to a release that supports the target SLES service pack.
- Verify that the intended SLES migration path is supported.
- Take a VM snapshot or ensure a reliable backup is available.
Check Service Pack Migration Readiness
Before starting a migration, review the available migration options and any potential issues.
Check the migration command's supported options:
zypper migration --helpWhere supported by the installed migration plugin, use:
zypper migration --queryThis can be used to inspect available migration targets without initiating the actual upgrade. Confirm that the query option is supported by your installed version before relying on it.
It is important to understand that not every SLES service pack can necessarily be skipped. Depending on the current release and available SUSE support entitlements, intermediate service pack migrations may be required.
Perform the Service Pack Upgrade
When ready, start the migration:
zypper migrationFollow the prompts, review the proposed package changes, and complete the migration.
After the migration finishes, reboot the server and verify that GMS is functioning correctly.
If additional service pack upgrades are required, repeat the process using the supported migration path.
4. Verifying Functionality After Updates
Regardless of which type of update was performed, always confirm that GMS is functioning correctly before considering the maintenance complete.
Check GMS Service Status
From the command line:
gms statusConfirm that the necessary GMS services are running.
Review the GMS Dashboard
Access the dashboard at:
https://your-server:8120
Verify the following:
- Both the GroupWise Sync Agent and Device Sync Agent are running.
- Dashboard statistics are being populated normally.
- The expected users are present.
- No new critical agent alerts are reported.
- Synchronization activity is occurring.
Run MCHECK
I recommend running an MCHECK general health check after updates to identify potential problems that may not be immediately obvious from the dashboard.
Test Mail Flow
Finally, verify that a mobile device can successfully send and receive email.
Remember: Just because the GMS services are running does not mean synchronization is functioning correctly. Always verify actual mail flow.
5. If an Update Fails
Even with careful preparation, updates occasionally fail. Problems can involve operating system dependencies, software compatibility, configuration issues, or incomplete upgrades.
If GMS does not function correctly after an update, review the service status, installation logs, and agent errors to identify the problem.
If the issue cannot be resolved within a reasonable amount of time, reverting to a known-good VM snapshot may be the most practical solution.
This is one of the primary reasons I recommend taking a snapshot before performing maintenance. Having a reliable recovery option can save hours of troubleshooting and unnecessary downtime.
For current compatibility requirements, known issues, and release-specific changes, refer to the GroupWise Mobility Service Release Notes.
System Build Recommendations
VMware Options
Disk Controllers
For GroupWise Mobility servers running on VMware, I recommend using VMware Paravirtual SCSI (PVSCSI) controllers. PVSCSI is designed for efficient virtualized disk I/O and is particularly well suited to workloads with substantial disk activity, such as GroupWise Mobility and its PostgreSQL database.
My preferred configuration for larger, heavily utilized GMS installations is:
| Controller | Configuration | Purpose |
|---|---|---|
| SCSI Controller 0 | VMware Paravirtual | Operating system disk |
| SCSI Controller 1 | VMware Paravirtual (Optional) | GMS data disk |
| SCSI Controller 2 | VMware Paravirtual (Optional) | Logging disk |
Using separate PVSCSI controllers can help reduce I/O contention at the virtual controller level by providing independent I/O queues for different workloads. This may be beneficial on heavily utilized GMS servers, although the actual performance improvement depends on the workload, hypervisor, and underlying storage infrastructure.
My Recommendation: For smaller installations, a single PVSCSI controller and virtual disk will generally be sufficient. For larger systems, I recommend considering separate virtual disks and PVSCSI controllers for the operating system, GMS data, and logging.
There is no specific user count at which this configuration becomes necessary. The administrator should evaluate the installation's size, workload, and performance requirements when determining how extensively to separate these components. The objective is to make strategic configuration improvements that can contribute to better overall performance, particularly when combined with other system optimizations discussed in this guide.
Important: I recommend selecting the PVSCSI controller when initially building the server. Do not casually change the boot disk from another controller type to PVSCSI after SLES has been installed. Depending on the configuration, changing the controller may require additional drivers, initramfs adjustments, or boot configuration changes and could render the server unbootable.
Disk Configuration
The following is my preferred disk configuration for larger GroupWise Mobility installations.
| Disk | Recommended Size | Controller | Purpose |
|---|---|---|---|
| Disk 1 | 100 GB | SCSI Controller 0 | Operating system |
| Disk 2 (Optional) | Size based on GMS data requirements, plus 25–30% for growth | SCSI Controller 1 | GMS data, typically mounted at /var |
| Disk 3 (Optional) | 50 GB | SCSI Controller 2 | Logging, mounted at /var/log |
These are starting recommendations, not fixed requirements. Actual disk sizes should be based on the number of users, database size, attachment storage, logging activity, and anticipated growth. For smaller installations, particularly those with approximately 50 users or fewer, a single disk may be perfectly adequate. There is little reason to introduce unnecessary complexity when the workload does not justify it. For larger installations, I prefer separating the GMS data onto a second virtual disk. On particularly busy systems, I also consider a third disk dedicated to logging.
Separate Disk or Partition for GMS Data
OpenText provides the following recommendation in its GroupWise Mobility documentation:
The largest consumers of disk space are the Mobility database (
/var/lib/pgsql) and Mobility Service log files (/var/log/datasync). You might want to configure the Mobility server so that/varis on a separate partition to allow for convenient expansion.
OpenText's recommendation is primarily about storage management and expansion. It does not specifically claim that separating /var will improve performance. However, I believe separating the GMS data is a worthwhile configuration strategy for larger installations, particularly when troubleshooting performance problems.
My typical approach is to create a second virtual disk and mount it at:
This places the PostgreSQL database, GMS attachment storage, and other files under /var on the second disk.
Some of the important GMS directories include:
/var/lib/pgsql- PostgreSQL database/var/lib/datasync/mobility/attachments- Attachment storage/var/log/datasync- GMS logging
Keep in mind that mounting a separate disk at /var also moves other operating system data stored under that directory onto the second disk. This is generally acceptable and provides flexibility when expanding storage in the future. Separating virtual disks does not automatically increase physical storage performance, particularly when the VMDKs share the same underlying datastore. However, using separate virtual disks and controllers may help reduce contention at the virtual I/O level and provides additional flexibility for storage management.
Optional Third Disk for Logging
One consideration when mounting the second disk at /var is that the PostgreSQL database and GMS log files will still reside on the same virtual disk. This can become important on larger systems, particularly when diagnostic logging is enabled. GroupWise Mobility can generate substantial logging activity. On heavily utilized systems, diagnostic logging can produce millions of log entries in a relatively short period.
That creates two potential concerns:
- Excessive logging can consume disk space and potentially affect the database or other GMS services.
- Heavy logging activity can compete with PostgreSQL and other GMS processes for storage I/O resources.
For larger, heavily utilized systems, I sometimes recommend creating a third virtual disk and mounting it at:
This separates logging from the primary GMS data disk. The advantages include independent log storage capacity, reduced risk of logging consuming database space, and the potential to reduce I/O contention between logging and database operations. The performance benefit depends on the underlying storage configuration. Separate virtual disks and controllers can provide additional isolation, but they do not eliminate contention at a shared physical datastore.
My Recommendation: I would not normally configure a third disk on a small GMS installation. For larger systems, particularly those experiencing performance problems or requiring extensive diagnostic logging, I consider it a worthwhile option.
General Storage Considerations
GroupWise Mobility can be very disk intensive, particularly on systems with large numbers of users and significant synchronization activity. Where multiple storage tiers are available, I recommend placing the GMS database and other heavily utilized data on the best-performing storage already available within the environment.
Storage configuration is only one component of GMS performance. The PVSCSI controller configuration, I/O scheduler, filesystem options, memory allocation, and other tuning recommendations discussed elsewhere in this guide should be evaluated together. No single configuration change guarantees improved performance. However, a series of carefully selected optimizations can collectively make a meaningful difference on a heavily utilized GroupWise Mobility server.
VMware Disk Provisioning: Thin vs. Thick
When configuring virtual disks for GroupWise Mobility, VMware provides several provisioning options. The provisioning method can affect disk performance, particularly on larger, heavily utilized GMS installations. In my experience troubleshooting poorly performing GroupWise Mobility servers, disk provisioning is one of several configuration factors that can contribute to performance problems. I've encountered production GMS environments where thin-provisioned disks were a significant concern, and I generally prefer Thick Provision Eager Zeroed for larger installations.
Understanding the Provisioning Options
Thin Provision
Disk space is allocated on the datastore as data is written, rather than allocating the entire virtual disk capacity upfront. Thin provisioning is convenient and efficient from a storage utilization standpoint. For smaller and moderately utilized GMS installations, it is generally adequate. However, allocating additional storage during write operations can introduce overhead. On heavily utilized systems, particularly those with substantial PostgreSQL database activity, this overhead may contribute to storage latency. Thin provisioning also introduces capacity management considerations. If multiple virtual disks are overprovisioned and the underlying datastore runs out of available space, the consequences can be severe.
Thick Provision Lazy Zeroed
The full capacity of the virtual disk is allocated when the disk is created, but the individual blocks are not zeroed until they are first written. This eliminates the need to allocate additional datastore capacity as the virtual disk grows, but first writes to previously unused blocks can still involve zeroing overhead.
Thick Provision Eager Zeroed
The full capacity of the virtual disk is allocated and zeroed when the disk is created. This eliminates the additional allocation and zeroing operations associated with first writes to previously unused disk regions. For workloads involving substantial disk write activity, such as PostgreSQL databases, this can provide more consistent write performance by avoiding those first-write operations.
My Recommendation
For smaller GroupWise Mobility installations, thin provisioning is generally adequate and offers the advantage of more efficient storage utilization. For larger, heavily utilized GMS installations, I recommend Thick Provision Eager Zeroed, particularly for the virtual disk containing the PostgreSQL database and other GMS data.
This recommendation is based on both VMware's documented disk provisioning behavior and my own experience troubleshooting production GroupWise Mobility environments. I've encountered severely underperforming GMS systems where thin provisioning was one of the contributing factors. While changing disk provisioning alone is not necessarily going to resolve every performance problem, it is one of several optimizations I consider when evaluating a system. The actual performance difference depends on the underlying storage infrastructure. Some high-performance SANs and modern storage arrays may minimize the overhead associated with thin provisioning, while other environments may exhibit more noticeable differences.
Capacity and Storage Considerations
Regardless of the provisioning method, ensure adequate datastore capacity is available. Thin provisioning requires particular attention because the total provisioned capacity of virtual disks can exceed the physical capacity available on the datastore. Thick Provision Eager Zeroed requires the full virtual disk capacity to be available when the disk is created, so storage requirements must be planned accordingly. If the environment offers multiple storage tiers, I prefer placing the GMS database on the highest-performing storage already available.
Final Considerations
Disk provisioning should be evaluated as part of the overall GMS configuration, alongside virtual disk controllers, I/O scheduler settings, filesystem configuration, memory allocation, and other performance-related settings. The objective is cumulative optimization. No single configuration change guarantees improved performance, but several carefully selected adjustments can collectively make a substantial difference on a heavily utilized GroupWise Mobility server. For larger installations, I prefer to eliminate avoidable sources of I/O overhead wherever practical. Thick Provision Eager Zeroed is one of the configuration choices I use toward that objective.
Boot Options / Firmware: BIOS vs. EFI
In VMware, under VM Options > Boot Options, you can select either BIOS or EFI as the virtual machine's firmware. Both options work with GroupWise Mobility Service, and neither provides a significant performance advantage for GMS itself.
My Recommendation: For new GroupWise Mobility installations, I recommend using EFI. It is the current firmware standard and provides support for newer boot and security capabilities.
For existing GMS servers already configured with BIOS, I recommend leaving them alone. There is generally no compelling reason to change a properly functioning production server from BIOS to EFI.
BIOS
BIOS is the legacy firmware option and remains functional for existing GroupWise Mobility installations. There is no need to rebuild or convert an existing BIOS-based server solely to adopt EFI.
EFI
EFI is my preferred option for new GroupWise Mobility installations. It supports modern boot configurations and additional security capabilities, including Secure Boot where supported and appropriately configured.
Important Considerations
Choose your firmware type when initially building the virtual machine.
Changing an existing installation from BIOS to EFI, or EFI to BIOS, is not simply a matter of changing the VMware firmware setting. The operating system's bootloader and disk configuration must support the selected firmware type. Changing this setting without the appropriate preparation can render the server unbootable. For existing production GMS servers, I recommend retaining the current firmware configuration unless there is a specific technical requirement to change it.
Supported Operating Systems and Upgrade Considerations
I generally recommend using the latest supported version of SLES 15 when deploying GroupWise Mobility Service. For current installations, my preference is SLES 15 SP7.
For historical reference, the following SLES versions have been used with GroupWise Mobility:
- SLES 15 SP4: Commonly used with GMS 18.3.x and 18.4.x. Some compatibility challenges were encountered with GMS 18.5.
- SLES 15 SP5: Released June 20, 2023. Widely used with GMS 18.5 and subsequent releases.
- SLES 15 SP6: An intermediate service pack supported by applicable newer GMS releases.
- SLES 15 SP7: The latest SLES 15 service pack as of this writing and my preferred operating system for current GMS deployments.
Always verify operating system compatibility with the specific GMS release before installing or upgrading.
Important GMS Upgrade Considerations
- GMS 14.x through 18.3.0: These older releases cannot be upgraded directly to GMS 18.3.1 or later. A new GMS server installation is required.
- GMS 18.3.1 and later: In-place upgrades to newer GMS releases are generally supported, provided the underlying SLES version meets the requirements of the target release.
- Older Installations: In-place upgrades are generally supported and recommended for GMS 18.3.1 and later. However, the older the installation, the greater the potential for compatibility issues involving SLES, Python, Django, and other dependencies. In some cases, deploying a new server may be more practical than upgrading an existing installation.
For current compatibility requirements and upgrade restrictions, refer to the GroupWise Mobility Service Release Notes.
File System Selection and Partitioning
SLES 15 defaults to Btrfs for the root filesystem. For GroupWise Mobility, I recommend changing this to EXT4, which remains the filesystem officially recommended by OpenText in the GroupWise Mobility 26.2 documentation.
Do not simply accept the default SLES partitioning configuration. Review the proposed partitions and configure the filesystem layout appropriately for your GMS deployment.
Historical Note: GMS 18.4 and Btrfs
Beginning with GMS 18.4, support was introduced for running load scripts on Btrfs and XFS filesystems. However, EXT4 remained the recommended filesystem, and that recommendation continues in GMS 26.2.
I personally prefer EXT4 for production GMS installations and see no compelling reason to deviate from OpenText's recommendation.
Separate Disk/Partition for GMS Data
If you utilize a 2nd partition for GMS data, it is important to understand the storage structure of GMS and where the data is kept. Per the documentation:
The largest consumers of disk space are the Mobility database (/var/lib/pgsql) and Mobility Service log files (/var/log/datasync). You might want to configure the Mobility server so that /var is on a separate partition to allow for convenient expansion. Another large consumer of disk space is attachment storage in the /var/lib/datasync/mobility/attachments directory.
Typically, with a 2nd disk, I mount it to the /var directory. This will put /var and all subfolders on the 2nd disk, including non-gms files located in /var. This is typically fine.
Possible 3rd Disk for Logging
The one "possible" downside of mounting disk2 to /var is that both gms data and all server logging (including GMS logging) will be on the same disk. There is potential for the partition to fill up due to the amount of logging that could be done by GMS (especially if you're in diagnostic logging mode). On very large systems I sometimes create a 3rd disk and mount it specifically to /var/log. That will prevent any excessive logging from affecting the GMS services.
All about SSL Certificates
SSL Certificates Name and Location
For GroupWise Mobility 18.3.1 and newer, the SSL certificate files are located in /var/lib/datasync. The following information is from the developers about each file and its purpose.
Used by Devices and Webadmin and should be replaced with a public certificate. This is the only certificate file you should normally need to replace.
Used internally by GMS and should NOT be replaced with your public certificate that is used for Devices & Webadmin.
Rarely used, but generated from gms_mobility.pem. It is mostly for backward compatibility with older devices that require the manual addition of the certificate. It is accessed via the user login of the webadmin.
Reference: Micro Focus TID 7025233: GMS 18.3.1 certificate files
Third-party SSL Certificates
It's nearly impossible to use self-signed certificates anymore. Most phones require trusted certs in order to communicate. I am not going to go into detail about how to generate the certificates, but this shows you what you need to do to take your existing third-party certificates and configure them on a GMS server. This is what you'll need:
-
The private key file (That you generated when you created the CSR to submit to your SSL vendor)
- Also of importance is to note that GMS requires that the Private Key file does NOT have a password on it. This is the exact opposite of what is required by the GroupWise Agents.
- The server certificate (Generally .crt file) from your SSL vendor
- The SSL Vendor's intermediate SSL Certificate.
Combining All Certificate and Key Files into a single PEM file
GMS requires that all of your certificate files are combined into a single PEM file. You basically concatenate all files together using the sequence below. Please note that you will need to use the name of your specific files, not the samples I have used.
# cat passwordless.key > gms_mobility.pem
# Ensure that you are using the Key File that does NOT have a password on it

# cat server.crt >> gms_mobility.pem
# This is the certificate provided by the SSL vendor

# cat intermediate.crt >> gms_mobility.pem
# This is the Intermediate certificate provided by the SSL vendor

# cp gms_mobility.pem /var/lib/datasync/

# gms restart
SSL Certificate Chain Considerations
One of the more frustrating aspects of installing third-party SSL certificates is getting the intermediate certificate chain correct. Depending on the certificate authority, you may receive multiple intermediate certificates, a bundled CA chain, or several files that appear to serve the same purpose.
The important thing is to include the correct intermediate certificates in the PEM file, in the proper order, without unnecessary or duplicate certificates. A certificate may appear to work in a browser while still reporting chain problems in an independent SSL test.
After installing or renewing a certificate, I recommend testing the public-facing GMS server using Qualys SSL Labs. Review the certificate chain results and correct any incomplete or incorrectly ordered chain before considering the installation finished.
Reference TID from Micro Focus
This Micro Focus TID is not completely accurate for GMS 18.3.1+, but the general process is the same and it does go into more detail about the entire process. Note the file name and location changes that I have outlined. How to configure Certificates from Trusted CA for Mobility (microfocus.com)
Starting / Stopping / Enabling / Disabling GroupWise Mobility
GroupWise Mobility services are managed from the Linux command line using the gms command. The Mobility Dashboard allows you to monitor service status, but it does not provide the ability to start or stop the services.
Under normal circumstances, gms restart is sufficient to restart GroupWise Mobility. However, I've encountered situations where a restart does not completely shut down all services, leaving the system in a problematic state. When troubleshooting these situations, I prefer to perform a controlled stop and start rather than relying on a restart.
- Run
gms stopto shut down GroupWise Mobility. - Wait approximately 20–30 seconds for the services to terminate.
- Run
gms statusand verify that all services have stopped. In my experience, the GMS status command typically reports these services asfailedwhen they are no longer running. - Once everything has stopped, run
gms start. - Run
gms statusagain to confirm that all services are running.
If services remain active after issuing gms stop, don't assume that the shutdown was successful. Investigate the remaining processes before attempting to restart GMS.
This approach has been particularly useful when troubleshooting synchronization problems or situations where GMS appears to be running but is not functioning correctly.
| Function | Command |
|---|---|
| Start GroupWise Mobility | gms start |
| Stop GroupWise Mobility | gms stop |
| Show GroupWise Mobility Status | gms status |
| Restart GroupWise Mobility | gms restart |
|
Enable GroupWise Mobility (enable GMS to start automatically with system) |
gms enable |
|
Disable GroupWise Mobility (prevent GMS from starting automatically with system) |
gms disable |
Troubleshooting GMS
Everything below this point relates to the general troubleshooting of a GroupWise Mobility system. Many issues you may experience are related to performance issues and resource exhaustion. The tips below are things I do to squeeze more performance out of my systems.
GMS Troubleshooting Tool: MCHECK
GroupWise Mobility has a tool called MCHECK that is used to troubleshoot a variety of different issues related to the day-to-day operation of a GMS system. If you are having any problems with GMS, a good rule of thumb is to run some basic tests with MCHECK and see if any problems are reported.
Documentation: Refer to the link below for product documentation:
https://www.novell.com/documentation/groupwise24/gwmob_guide_admin/data/admin_mgt_mcheck.html
NOTE: The tool DSAPP that was used by older versions of GroupWise Mobility is deprecated and will not work on current versions of GroupWise Mobility. MCHECK is fully supported and actively developed with new features and options in each new version of GMS. Trying to run DSAPP will leave you frustrated and angry, even if TIDs you're reading make reference to it and sound like it should work.
MCHECK - General Health Check
MCHECK has quite a few different options and overall is pretty useful. I do not go into extensive detail on all of the options here (refer to the documentation). However, the most useful check is the "General Health Check" because of the number of different checks it runs in a single operation.
The General Health Check runs and displays a series of tests on the GMS server. After all the checks are run, you can view more detailed information about each check in the mcheck log file.
Launching MCHECK & Running a General Health Check
MCHECK is a command line tool that presents you with a text base menu. It is a python application and uses python to launch. The easiest way to run it is by changing to the folder where the MCHECK tool is located and running it from there.
- Open a Linux Command line on the GMS server.
- Change to the /opt/novell/datasync/tools/mcheck folder:
mhcfs03# cd /opt/novell/datasync/tools/mcheck3. Run the command to launch mcheck:
mhcfs03# python3.11 mcheck.pyc4. The main menu for MCHECK will load:
MCheck (Version: 26.2) - Running as root
--------------------------------------

     1. System
     2. Users
     3. Database
     4. Checks & Queries

     0. Exit

Select option:- Choose "4. Checks & Queries" from the menu
- This will bring you to the Checks & Queries Submenu where you will see the "General Health Check Option"
MCheck (Version: 26.2) - Running as root
--------------------------------------
Checks & Queries

     1. General Health Check
     2. GW pending events by User (consumerevents)
     3. Mobility pending events by User (syncevents)
     4. Generate csv list of inactive users
     5. Dump critical alerts

     0. Back

     Select option:
Choose "1. General Health Check". This will start the process and generate the results as shown below:
===Running General Health Check===
--------------------------------------
Checking Mobility Services...      Passed
Checking Trusted Application...    Passed
Checking Required XMLs...          Passed
Checking XMLs...                   Passed
Checking PSQL Configuration...     Passed
Checking Proxy Configuration...    Passed
Checking Disk Space...             Passed
Checking Memory...                 Warning
Checking VMware-tools...           Passed
Checking Automatic Startup...      Passed
Checking Database Schema...        Passed
Checking Database Maintenance...   Passed
Checking Reference Count...        Failed
Checking Databases Integrity...    Failed
Checking Targets Table...          Passed
Checking Certificates...           Warning

The remaining checks may take a while.
Please be patient...

Checking Disk Read Speed...        Passed
Checking Server Date...            Passed
Checking RPMs...                   Passed
Checking Nightly Maintenance...    Passed

Press Enter to continue
MCHECK Log Files & Viewing Problems Found
The log files for MCHECK provide more detail about the issues that are reported. Since the checks cover a lot of different things, it's difficult to outline every possible scenario here. The best thing to do is look at the logs, view the detailed information about any specific issue, and determine how to proceed from there. If the issue is over your head or beyond your comfort level, don't hesitate to reach out. The MCHECK log files are located here:
/opt/novell/datasync/tools/mcheck/logsFor the General Health Check log files, look for the file(s) "generalHealthCheck_" + Date/Timestamp + ".log". The file will be timestamped with the date and time the check was run. After you run a general health check, just check the most recent log file. Below is an example of the file listing of the log folder.
-rw-r--r-- 1 root root     0 Jul 18  2022 generalHealthCheck_2022-07-18T23:18:20.log
-rw-r--r-- 1 root root 27817 Nov  2  2022 generalHealthCheck_2022-11-02T05:40:05.log
-rw-r--r-- 1 root root 27516 Jan  4 22:13 generalHealthCheck_2024-01-04T22:12:23.log
-rw-r--r-- 1 root root 27694 Jan 14 19:45 generalHealthCheck_2024-01-14T19:44:44.log
-rw-r--r-- 1 root root 27671 Jan 14 19:48 generalHealthCheck_2024-01-14T19:47:59.log
-rw-r--r-- 1 root root 55336 Jan 14 20:21 generalHealthCheck_2024-01-14T20:19:53.log
-rw-r--r-- 1 root root     0 Jan 14 21:05 generalHealthCheck_2024-01-14T21:05:55.log
-rw-r--r-- 1 root root 27668 Jan 14 21:09 generalHealthCheck_2024-01-14T21:08:51.log
Memory Considerations
Over the years, the most common problems I've encountered with GroupWise Mobility Service (GMS) have been performance-related. I've spent considerable time troubleshooting and optimizing GMS installations, and insufficient memory has consistently been one of the biggest contributing factors. In my experience, the majority of GMS performance problems I encounter involve inadequate memory allocation, either directly or in combination with other configuration issues.
When GroupWise Mobility was first introduced, it was a relatively lightweight application that required very few system resources. That is no longer the case. Modern GMS installations can consume substantial amounts of CPU and memory, depending on the number of users, devices, mailbox sizes, synchronization activity, and overall workload. One of the biggest mistakes I encounter is assuming that the minimum published system requirements represent an appropriate configuration for a heavily utilized production environment.
Memory Sizing Recommendations
The following compares OpenText's published sizing guidance with the recommendations I've developed through real-world experience supporting production GMS environments.
| OpenText Documentation | My Real-World Recommendations |
|---|---|
| 8 GB RAM for approximately 300 devices | 8 GB RAM is generally adequate for approximately 20–25 users. |
| 12 GB RAM for up to 750 users and 1,000 devices | For approximately 100 users, I generally recommend a minimum of 16 GB RAM. |
| For 300 or more users, I frequently recommend 24–32 GB RAM, sometimes more depending on the workload. |
Important: These are practical sizing recommendations, not absolute requirements. User count alone does not determine memory consumption. Device count, mailbox sizes, synchronization patterns, and database activity can significantly affect resource utilization.
I've encountered larger installations requiring considerably more memory than the published requirements suggest.
Symptoms of Insufficient Memory
When a GMS server begins running short of available memory, several symptoms may appear:
- Significant delays receiving email on mobile devices.
- Synchronization becoming extremely slow or stopping altogether.
- System-wide synchronization problems affecting multiple users.
- GMS services appearing to be running normally while synchronization is malfunctioning.
- Excessive swap utilization and substantial disk activity.
- Severe system latency or periods where the server becomes nearly unresponsive.
- A reboot temporarily restoring normal operation.
I've encountered situations where memory exhaustion caused GMS to malfunction, including synchronization failures and other unexpected behavior. On virtualized SLES servers, I've also observed extremely severe performance degradation when the operating system begins actively swapping memory to disk. In some cases, the server becomes so unresponsive that the behavior resembles a denial-of-service condition. These problems can be particularly disruptive because the GMS services may still appear to be running, even though users are experiencing significant synchronization failures.
My Recommendation: Before spending substantial time troubleshooting CPU performance, PostgreSQL behavior, or other GMS components, verify that the server has adequate memory.
Diagnosing Low Memory
There are several Linux commands that can help determine whether a GroupWise Mobility server is experiencing memory pressure.
1. Check Memory and Swap Usage
Start with:
free -mThis displays physical memory and swap utilization in megabytes.
For a more readable representation using GB and MB, you can also use:
free -hExample:
               total        used        free      shared  buff/cache   available
Mem:           19811       12727         409         650        6675        7083
Swap:           8188        1708        6480
Understanding the Results
In this example, the server has approximately 20 GB of physical memory.
Physical Memory:
- Total: 19,811 MB
- Used: 12,727 MB
- Free: 409 MB
- Available: 7,083 MB
Swap Space:
- Total: 8,188 MB
- Used: 1,708 MB
- Free: 6,480 MB
Linux aggressively uses available memory for filesystem caching and other purposes. Therefore, a low value in the free column does not automatically indicate that the server is running out of memory. The available column is generally a better indicator of how much memory the operating system can make available to applications without significant swapping. In this example, approximately 7 GB remains available, so the physical memory statistics alone do not indicate an immediate shortage.
This is something I would investigate further. Approximately 1.7 GB of memory has been moved into swap space. That doesn't necessarily mean the server is actively swapping at this moment, or that physical memory was completely exhausted. Linux can move less-active memory pages to swap as part of its normal memory management behavior. However, swap utilization tells us that the operating system has previously moved memory pages out of physical RAM and onto disk. For a performance-sensitive GMS server, I consider that useful diagnostic information. My preference is to provide sufficient RAM and configure the operating system so that swapping is minimized wherever practical.
2. Check for Active Swapping with VMSTAT
The free command provides a snapshot of memory utilization, but it doesn't tell us whether the server is actively swapping memory. To investigate further, use:
vmstat 1 10This collects memory and system activity statistics once per second for 10 samples.
Example output:
procs -----------memory---------- ---swap-- -----io---- -system-- ------cpu-----
 r  b   swpd   free   buff  cache   si   so    bi    bo   in   cs us sy id wa st
 1  0 1748992 420000  12000 5600000    0    0    10    25  150  300 10  3 86  1  0
 2  1 1748992 390000  12000 5600000  256  512   270   550  250  500 20  5 65 10  0
 3  2 1751040 350000  12000 5500000 1024 2048  1100  2200  400  800 25  8 47 20  0
The most important columns for this discussion are:
| Column | Description |
|---|---|
swpd |
Amount of virtual memory currently used as swap. |
free |
Unused physical memory. |
si |
Memory swapped in from disk, measured in KB per second. |
so |
Memory swapped out to disk, measured in KB per second. |
wa |
Percentage of CPU time spent waiting for I/O. |
b |
Number of processes blocked while waiting for resources, typically I/O. |
Pay particular attention to the si and so columns. If these values are consistently above zero, the operating system is actively moving memory between RAM and swap. On a heavily utilized GroupWise Mobility server, sustained swapping can introduce substantial latency and cause serious performance problems. High swap activity combined with increased I/O wait, blocked processes, and synchronization delays is a strong indication that memory pressure may be affecting the server.
Note: The first line of vmstat typically reports averages since the last reboot. Focus on the subsequent samples when evaluating current activity.
3. Review Memory Usage by Process
Use the Linux top command:
top
This provides a real-time view of CPU and memory utilization. Within top, press Shift + M to sort processes by memory consumption.
On a GroupWise Mobility server, pay particular attention to processes associated with:
- PostgreSQL (
postgres) - GroupWise Mobility Python processes (
python3) - Other GMS-related services
PostgreSQL uses multiple processes and shared memory, so be careful when interpreting the individual memory values. Simply adding the reported memory usage of every PostgreSQL process can overstate actual physical memory consumption. The objective is to identify processes consuming substantial resources and determine whether overall memory demand is placing pressure on the operating system.
4. Check Historical Memory Pressure
A memory snapshot immediately after a reboot is not particularly useful when evaluating normal production utilization. After a restart, filesystem caches are relatively empty, some application activity has not resumed, and the system may not yet have reached its normal operating workload.
Use:
uptimeThis tells you how long the server has been running. I generally prefer to evaluate memory statistics after the server has been operating under normal production conditions for at least a day or two. If the server has been running for several weeks and is reporting substantial swap utilization, that is worth investigating, even if it is not actively swapping at the exact moment you check.
To observe memory activity over a longer period, you can also run:
vmstat 5 60This collects statistics every five seconds for approximately five minutes. For intermittent performance problems, collecting statistics during the actual period of poor synchronization is considerably more useful than examining the server after everything has returned to normal.
Memory Allocation and Virtualization
When GroupWise Mobility is running on VMware or another virtualization platform, memory allocation deserves additional attention. Make sure the virtual machine has sufficient physical memory available from the host and is not experiencing memory contention caused by other virtual machines. Hypervisor-level memory reclamation, ballooning, or host swapping can introduce additional performance problems that may not be immediately obvious from the Linux memory statistics alone. A virtual machine may report reasonable memory availability internally while still experiencing performance degradation due to memory pressure at the hypervisor level. For heavily utilized GMS servers, I prefer predictable memory availability rather than relying on aggressive memory overcommitment.
Final Recommendations
Based on my experience supporting production GroupWise Mobility environments:
- Don't assume the published minimum RAM requirements are sufficient for a busy production server.
- Size memory according to the actual workload, not simply the number of users.
- Pay attention to swap utilization, even when the server is not actively swapping.
- Use
vmstatto determine whether swapping is actively occurring. - Evaluate memory statistics after the server has been running under normal production conditions.
- Check for memory contention at the virtualization layer.
- Investigate memory pressure before assuming that CPU or database performance is the primary problem.
My objective is to keep GMS operating primarily in physical memory and avoid unnecessary swapping.
GroupWise Mobility relies heavily on PostgreSQL and performs substantial database activity. Memory pressure and excessive swapping can have serious consequences for synchronization performance and overall system stability. In the Linux Swappiness section later in this guide, I explain why I also recommend reducing the default vm.swappiness setting from 60 to 1 as part of my overall GMS performance optimization strategy. Adequate memory allocation and appropriate Linux memory management settings work together. Neither replaces the other.
CPU Considerations
GroupWise Mobility relies heavily on the PostgreSQL database. Databases in general can be CPU intensive. CPU requirements go up with user count, device count, and data sizes.
From The GroupWise Documentation
- x86-64 processor
- 2.8 GHz multi-processor system with a 4-Core CPU recommended
From Real-World Experience
4 Cores are generally adequate on a smaller system, but may not be practical at all on larger systems with hundreds of users. What you will find is that your Mobility Server can run very high CPU utilization with average day-to-day usage. Adding CPUs can help with this situation and help the system run better. The primary consumers of CPU resources are typically the PostgreSQL database and the Python processes associated with GroupWise Mobility.
Symptoms of an overburdened CPU in a GroupWise Mobility Server
Ensure that your RAM allocations are adequate before troubleshooting the processor. RAM accounts for most performance problems. After you are confident you have enough RAM, note the following symptoms that could indicate the CPU allocations are too small.
- Very high CPU utilization at the console.
- Latency sending and receiving email on phones, system-wide.
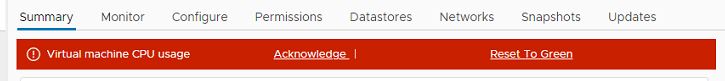
- If virtualized, CPU alerts in VMWare.
The Linux "top" Command
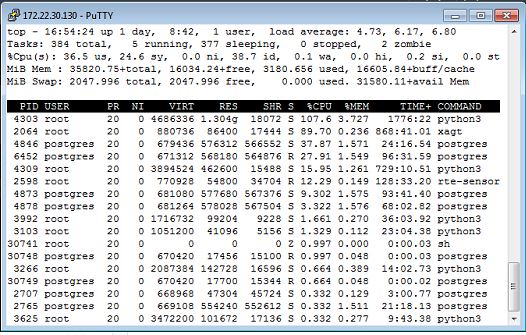
The "top" command shows the most heavily utilized processes in real-time on a Linux server. Let's take a look at this screenshot below. It outlines the heaviest processes that are hitting the CPU.
As a point of reference, this server is a very busy server. It currently has 36GB Ram assigned, 6 CPUs, and 400 users provisioned. I am troubleshooting high utilization and complaints from the customer.
CPU Count / "top" analysis
Based on the output of the top command, the majority of CPU utilization is attributed to python3 and postgres processes. Since GroupWise Mobility is implemented in Python and relies on PostgreSQL, this indicates that GroupWise Mobility workloads are the primary consumers of CPU resources on this server. Increasing the vCPU allocation from 6 to 8 cores is a reasonable step to improve overall performance.
In large GroupWise Mobility deployments, sustained high CPU utilization can occur even when memory is adequately sized. Environments supporting approximately 500 users per server have shown consistently high CPU usage when limited to 8 vCPUs. Increasing the vCPU allocation to 12 cores in properly resourced VMware environments can result in an immediate and noticeable reduction in sustained CPU utilization and improved system responsiveness. This approach should be evaluated in the context of host capacity and overall cluster load.
Caution on vCPU Allocation in Virtualized Environments
Adding more vCPUs to a virtual machine does not automatically result in better performance. In some cases, excessive CPU allocation can actually make performance worse due to scheduling overhead and resource contention.
One important consideration is the physical CPU configuration of the virtualization host, particularly the number of physical cores per processor and the NUMA (Non-Uniform Memory Access) architecture. On multi-socket servers, assigning more vCPUs than can fit within a single physical NUMA node may cause the virtual machine to span multiple NUMA nodes, potentially introducing additional memory-access latency.
CPU Ready time is another important consideration, particularly on heavily utilized VMware hosts. A virtual machine with more vCPUs may experience increased scheduling delays if sufficient physical CPU resources are not available.
That said, I've seen dramatic improvements in GroupWise Mobility performance simply by increasing the number of allocated vCPUs, particularly on larger systems with heavy synchronization workloads.
My recommendation is to understand the underlying physical hardware, review CPU utilization and scheduling contention, and increase vCPU allocations where the workload justifies it. Don't arbitrarily limit the number of vCPUs, but don't assume that assigning more is always better either.
Misc Performance Tuning
Additional Linux and storage performance considerations
There are four other items that can be tuned if you are not getting the performance you need out of your system. These are core Linux settings related to the performance that go away from the standard defaults. In many cases, the defaults are adequate. But if you are looking to squeeze a little more performance out of your system, these are options you can consider.
Performance Tuning Topics
Important Note
These are advanced system settings, and you should fully understand that a misstep here could cause severe problems with your system. Please approach with caution.
I/O Scheduler: "none"
Linux storage performance tuning for GroupWise Mobility Service
For GroupWise Mobility servers running on VMware, I recommend using the none I/O scheduler to avoid unnecessary guest-level disk scheduling. This is one of several Linux configuration adjustments worth considering when optimizing a heavily utilized GroupWise Mobility server.
Why Change the I/O Scheduler?
GroupWise Mobility can generate substantial disk activity, particularly from its PostgreSQL database, synchronization processes, and logging. On larger installations, storage performance can become an important factor in how quickly the system processes activity from connected devices. Linux uses an I/O scheduler to manage how disk requests are handled. On a physical server, this can help organize requests before they reach the storage hardware. However, when Linux is running as a virtual machine, there is another layer involved.
VMware already has its own storage stack responsible for
managing I/O requests to the underlying physical storage.
Depending on the environment, having the guest operating
system perform additional scheduling may introduce overhead
without providing a meaningful benefit. Using the
none scheduler removes that additional scheduling
layer within the guest, allowing requests to pass through
without the guest performing its own request reordering.
This does not bypass VMware's storage management, nor does
it eliminate the importance of fast underlying storage.
It simply avoids additional scheduling work inside the
Linux virtual machine.
Less Guest-Level Overhead
Avoids unnecessary scheduling operations inside the virtual machine.
Storage Stack Efficiency
Allows the hypervisor and underlying storage system to manage request handling.
Potential Performance Benefit
May reduce unnecessary overhead for workloads generating substantial disk activity.
When Does This Recommendation Apply?
My recommendation is primarily directed at GroupWise Mobility servers running as virtual machines on VMware. Larger GMS installations, particularly those with substantial PostgreSQL and synchronization activity, are more likely to benefit from reviewing their storage configuration. This is not a guarantee of improved performance. Smaller installations may not see any noticeable difference, and the default scheduler may already provide acceptable results. The objective is to eliminate unnecessary processing where it makes sense, while recognizing that actual storage performance depends on the complete environment.
Configuring the I/O Scheduler
On SLES, the I/O scheduler can be configured through a udev rule. The following procedure uses the standard SUSE rules file as the starting point.
Copy the Existing udev Rules File
Copy the system-provided scheduler rules
file into /etc/udev/rules.d/
so your configuration is maintained
separately from the vendor-supplied file.
cp /usr/lib/udev/rules.d/60-io-scheduler.rules /etc/udev/rules.d/Edit the Copied File
Open the copied file:
vi /etc/udev/rules.d/60-io-scheduler.rulesLocate the section identified by the following comment:
# --- EDIT BELOW HERE after copying to /etc/udev/rules.d ---Set the Scheduler to none
Add the following rule in the editable section, before the existing default scheduler rules:
KERNEL=="sd[a-z]*", ATTR{queue/scheduler}="none", GOTO="scheduler_end"The relevant section of the rules file may look similar to this:
# --- EDIT BELOW HERE after copying to /etc/udev/rules.d ---

KERNEL=="sd[a-z]*", ATTR{queue/scheduler}="none", GOTO="scheduler_end"

# Additional device patterns may be needed
# depending on the virtual disk controller.
# KERNEL=="vd[a-z]*", ATTR{queue/scheduler}="none", GOTO="scheduler_end"
# KERNEL=="xvd[a-z]*", ATTR{queue/scheduler}="none", GOTO="scheduler_end"
The GOTO="scheduler_end"
directive prevents later rules in this
file from overriding the selected scheduler.
Reboot the Server
After saving the configuration, reboot the server so the rule is applied when the devices are initialized.
rebootDevice Naming Considerations
The rule shown above uses the device pattern
sd[a-z]*, which applies to devices
such as sda, sdb,
and sdc.
Depending on the virtual disk controller and
storage configuration, your system may use
different device names, such as
vda or nvme0n1.
In those cases, the device matching pattern
must be adjusted accordingly.
Important: udev device matching patterns use glob-style matching rather than regular expressions. Confirm the actual device names on your system before applying the rule.
Verify the I/O Scheduler
After rebooting, check the active scheduler for the appropriate disk:
cat /sys/block/sda/queue/scheduler[none] mq-deadline
The scheduler shown inside square brackets
is the currently active scheduler.
In this example, none is active.
If your server has additional disks, check those devices as well:
cat /sys/block/sdb/queue/scheduler
cat /sys/block/sdc/queue/scheduler
If none is not active,
verify that the udev rule matches the
correct device names and that another
rule is not overriding the configuration.
My Recommendation
For virtualized GroupWise Mobility servers
running on VMware, I recommend considering
the none I/O scheduler as part
of your overall performance configuration.
Verify the setting after rebooting rather than assuming that the configuration was applied successfully.
Keep in mind that this is only one part of the overall storage performance picture. Fast underlying storage, proper virtual disk configuration, and sufficient system resources remain important.
As with any performance tuning adjustment, the actual benefit depends on the workload and the environment. This setting should not be viewed as a guaranteed performance improvement.
File System Mount Option: "noatime"
Reducing unnecessary filesystem I/O on GroupWise Mobility servers
Further reduce unnecessary file access timestamp updates
by adding the noatime mount option to
the appropriate filesystem entries in
/etc/fstab.
Why Consider noatime?
Linux filesystems maintain access timestamps that record
when files are read. Historically, these updates could
generate unnecessary disk I/O. SLES 15 typically uses the relatime mount
option, which significantly reduces this overhead.
However, access-time updates still occur under certain
conditions. Using noatime eliminates these updates
and can provide an additional reduction in disk I/O,
particularly on systems with substantial filesystem
activity.
relatime
The typical SLES 15 default. Reduces timestamp updates significantly while still allowing updates under certain conditions.
noatime
Eliminates file access timestamp updates, reducing additional metadata writes associated with file access.
Configuring /etc/fstab
This is done in the /etc/fstab file. The following shows a typical
/etc/fstab configuration.
gmsserver:~ # cat /etc/fstab

UUID=fa9c8105-065f-4dfa-9766-95e72cb397a5 swap swap defaults 0 0
UUID=9315ebe4-d560-4249-842f-71524c041854 / ext4 defaults,noatime 0 1
UUID=44075e18-79d8-47bb-8b0e-0e39e027a0fc /var/log ext4 noatime,data=ordered 0 2
UUID=17d4970f-a4a3-4664-9170-922cffc9989f /var/lib ext4 noatime,data=ordered 0 2
UUID=38faf7aa-0286-4fe8-925e-7517c5bf8d94 /root ext4 noatime,data=ordered 0 2
UUID=D00B-3D8F /boot/efi vfat utf8 0 2
The above shows a typical /etc/fstab
file. You can see the various file systems being mounted. The place for noatime is after the file
system type, which you can see here is ext4. Any mount options are placed here in the file, and
multiple directives are separated with a comma. You might see a directive called defaults.
Or you may have some other directives such as what you
see here, data=ordered. Just append that with a comma and add
noatime.
Applying the noatime Option
Locate the Entry
Identify the filesystem and its current
mount options in /etc/fstab.
Add noatime
Append noatime to the existing
mount options, separating multiple options
with commas.
Apply on Reboot
Save the configuration. The new option takes effect when the filesystem is mounted during the next boot.
For example, if the current options are
defaults, change them to
defaults,noatime. If the entry already contains another option,
such as data=ordered, include
noatime as an additional
comma-separated option. When the system boots next, the parameter
will take effect as the file systems are mounted.
My Recommendation
For GroupWise Mobility servers with substantial
filesystem activity, noatime is
another configuration option worth considering
to reduce unnecessary disk writes. SLES 15 already uses relatime in
typical configurations, so much of the historical
access-time overhead has already been reduced.
The additional benefit of noatime
will depend on the workload. As with the other performance recommendations
in this guide, the objective is to eliminate
unnecessary overhead where practical rather
than assume that any single adjustment will
produce a dramatic improvement.
Linux Swappiness
Memory management configuration for GroupWise Mobility Service
Linux swappiness controls how aggressively the operating system moves memory pages to swap rather than retaining them in physical RAM. The default value on SLES 15 is typically 60. For a database-intensive application like GroupWise Mobility, I recommend reducing this value to 1 to minimize unnecessary swapping without disabling it entirely.
vm.swappiness = 1: the minimum amount of swapping without disabling it entirely
Find Your Current Swappiness Setting
There are two ways to check the current Linux swappiness setting. Both commands provide the same information.
Both commands display the currently active swappiness value. The only difference is how the result is presented.
Change the vm.swappiness Value
This command will put the setting into effect immediately, however it will not stick after a reboot:
# echo 1 > /proc/sys/vm/swappinessTo permanently make the change on your server, do the following:
Create a dedicated configuration file:
vi /etc/sysctl.d/90-gms-swappiness.confAdd the following line to the file:
vm.swappiness = 1Save the file and apply the configuration:
sysctl -p /etc/sysctl.d/90-gms-swappiness.confThe setting takes effect immediately and persists across reboots. No reboot is required.
Confirm the vm.swappiness Value
Confirm the setting is correct by issuing the following command:
# sysctl vm.swappinessvm.swappiness = 1Reference Article
Reference the following web page for a bigger discussion on this topic. Understanding VM Swappiness. From this page, you can find the following excerpt:
"The value of 60 is a compromise that works well for modern desktop systems. A smaller value is a recommended option for a server system, instead. As the Red Hat Performance Tuning manual points out, a smaller swappiness value is recommended for database workloads. For example, for Oracle databases, Red Hat recommends a swappiness value of 10. In contrast, for MariaDB databases, it is recommended to set swappiness to a value of 1 "
Because GroupWise Mobility is a very heavy PostgreSQL Database application, it makes sense to apply the same logic to a GMS server. And this is why I suggest setting this value to 1.
Background on why I started making this setting change
Over the years, with virtual Linux systems in general, I have found that if the memory is depleted and the system has to start swapping memory to disk, the server often completely chokes and can become non-responsive for several minutes. This creates a production outage and a system emergency as you scramble to figure out what happens. My goal with this setting is to minimize this behavior and prevent any sort of outage.
Storage Hardware / SAN Tiered Storage
Storage performance considerations for GroupWise Mobility Service
Please put your GMS system on the fastest storage available to you. GMS is very disk intensive. A slow disk could cripple your system.
My Recommendation
GroupWise Mobility relies heavily on PostgreSQL and performs substantial disk I/O during normal synchronization activity. Storage performance should be a priority when designing or optimizing a GMS server. Where multiple storage tiers are available, place the GMS database and other heavily utilized data on the fastest appropriate storage tier. Slow storage can become a significant bottleneck, particularly on larger installations with heavy synchronization activity.
Diagnostic Logging and Finding Problems
IMPORTANT WARNING: Diagnostic Logging Can Severely Impact Performance
Diagnostic logging is essential when troubleshooting difficult GroupWise Mobility synchronization issues. However, it generates an enormous amount of log activity and can have a significant impact on system performance, especially on larger or heavily utilized GMS servers.
If performance is already part of the problem, enabling Diagnostic logging may make the situation substantially worse. Use it with caution, enable it only when necessary to capture diagnostic information, and return logging to the normal Info level as soon as troubleshooting is complete.
Helpful Tips about Logging
- If you're troubleshooting GMS, also ensure that your POA's are in Verbose logging mode so you can troubleshoot that side if needed.
- Unless you are looking for specific historical data or trends, old log files are not that useful in most cases. Sometimes it is helpful to shut down GMS, remove (or move) all the log files in /var/log/datasync (and subfolders) and get a clean start for simplicity's sake. The amount of logging is overwhelming, so a clean start makes it easier to know you're looking at the right data.
-
When troubleshooting specific sync issues, it's important
to have some information handy relevant to the situation:
- Date/Time of the issue or message that was sent but not synced or received.
- Subject Line of messages that might not be syncing.
- Email recipient for problematic message.
- One additional strategy you could use on a very busy system is to ensure that the gms log files are on a different disk partition than the gms data. This would balance the disk writes across different devices and theoretically minimize the hit on the primary gms data partition. The way I have outlined above in the system build recommendations, you will accomplish this by having 2 or even 3 disks. If you've built a system with a different partitioning strategy, you may have to improvise and adjust based on how it is configured. If the system is already running, completely changing the partitioning strategy is not practical or possible. But you could add another VMDK file (assuming VMware) to the server and partition it and mount it to the gms log location which is /var/log/datasync. If you already have the main GMS data partitioned separately, and /var/log is set to the system partition, then this suggestion would be less applicable.
Note About Changing LOG Settings
- Changing the log level requires a GMS restart, which presents a challenge when troubleshooting intermittent problems. Restarting GMS may temporarily resolve the very issue you're trying to diagnose. My recommendation is to enable Diagnostic logging, restart GMS, and allow the system to run until the problem occurs again. This ensures that detailed logging is already enabled when the issue returns, providing the information needed to investigate the underlying cause. Once the issue has been resolved, return logging to the normal Info level to avoid unnecessary system overhead.
Idle Threads
You can view the logs in real time to see how many threads are in use and how many are idle. It can be surmised that if you have only one or two idle threads, or if all threads are completely consumed, your system may be experiencing performance issues and slow sync times. Monitor the number of idle threads by following the mobility-agent.log file with this command:
mobility:~ # tail -f /var/log/datasync/connectors/mobility-agent.log | grep -i 'Idle Threads'This will display a current view of your relevant log file and show you how many threads are idle. Here are outputs from two different servers for analysis. In the first one, you can see that there is consistently only 1 of 21 threads available. In the second one, there are consistently 12 of 20 threads available.
Server Example 1
2024-02-02 14:00:17.751 INFO [CP Server Thread-51] [DeviceInterface:302] [userID:] [eventID:] [objectID:] [] Idle threads = 1 / 21.
2024-02-02 14:00:18.396 INFO [CP Server Thread-40] [DeviceInterface:302] [userID:] [eventID:] [objectID:] [] Idle threads = 1 / 21.
2024-02-02 14:00:18.466 INFO [CP Server Thread-37] [DeviceInterface:302] [userID:] [eventID:] [objectID:] [] Idle threads = 1 / 21.
2024-02-02 14:00:34.627 INFO [CP Server Thread-66] [DeviceInterface:302] [userID:] [eventID:] [objectID:] [] Idle threads = 1 / 21.
Server Example 2
2024-02-02 14:04:02.361 INFO [CP Server Thread-56] [DeviceInterface:302] [userID:] [eventID:] [objectID:] [] Idle threads = 13 / 20.
2024-02-02 14:04:02.669 INFO [CP Server Thread-47] [DeviceInterface:302] [userID:] [eventID:] [objectID:] [] Idle threads = 12 / 20.
2024-02-02 14:04:03.198 INFO [CP Server Thread-43] [DeviceInterface:302] [userID:] [eventID:] [objectID:] [] Idle threads = 12 / 20.
There is a TID from Opentext that discusses this a little bit, and suggests that if you consistently have low threads, you may want to increase the threads. However they also recommend not exceeding 20 threads, which seems to be the predefined default. You can view that TID here: https://support.microfocus.com/kb/doc.php?id=7014654
If you are experiencing sync issues, and you see that your threads are exhausted, here is what I would suggest:
- Monitor the threads for a while and see if they clear up or the situation improves on its own. Just because they're low does not mean there is an issue. But it is something to be aware of.
- Restart GMS and immediately monitor the threads again to see what kind of impact that makes. Note the differences with the thread usage before and after the restart. If a situation existed where threads malfunctioned, a restart of GMS would immediately clear that up and allow the system to utilize all threads again, which will help performance.
- Note that thread info is not logged unless you have Diagnostic logging enabled in the GMS dashboard.
Mobility Agent "appears to be hung"
This will tell you if you have any threads that are actually hanging or have hung in the past. If you have threads that are hanging, this is a good reason to open an SR and get tech support involved so they can identify the cause of the hang. If threads are hanging, it will gradually bring your system to a halt as more threads will also likely hang until no more threads are available.
zgrep on the archived logs
this command will query all of the .gz files for the mobility agent. the .gz files are old copies of the logs that have been compressed. zgrep allows you to query inside them without extracting them first.
mobility: # cd /var/log/datasync/connectors
mobility: # zgrep -i "appears to be hung" mobility-agent.log*
grep on the current log file
This command will monitor the existing file and display any results, live as they happen.
mobility: # tail -f /var/log/datasync/connectors/mobility-agent.log | grep -i "appears to be hung"GroupWise Mobility Server Rebuild: A Last Resort for Persistent Sync Issues
A practical recovery procedure when conventional troubleshooting has failed
THIS IS A LAST RESORT SUGGESTION
This procedure is intended for situations where persistent synchronization problems cannot be resolved through normal troubleshooting.
Sometimes you run into issues where user devices just don't sync. Or things seem stuck. Or you beat your head on the wall for 3 days trying to diagnose and troubleshoot the situation and cannot make any headway. Troubleshooting system-wide sync issues is a nightmare. There are potentially millions of lines of debug data in your log files. Trying to find the cause is nearly impossible. Yes, you can get the debug logs to Tech Support, but you're going to have at least a couple days turn-around time or more. Do you want to wait that long, or do you want to just rebuild the server and move on with your life? Back and forth with tech support can turn a situation into weeks of frustration.
The reality is, if you've covered all the other bases in this document, and you're still having issues, sometimes it's actually easier to just bite the bullet, deploy a new GMS server from scratch, and reprovision all of the users. This section is intended to help you rebuild your system with minimal time investment.
20,000 ft Overview
The concept behind this process is not a typical migration to a new server. I take a slower approach with that. This is a shotgun wedding, get it done, cut out the BS. It's possible to rebuild a GMS server from scratch in 2 hours. Then you just have to wait for users to provision and you're back in business. But you need to do a little bit of prep work before you just abandon the old server. Otherwise you will have to scramble to find the stuff during and after the install. I've outlined all the items you need to concern yourself with in order to get this process turned around quick.
This assumes the following:
- You'll be keeping the same IP address and all other details of the existing server.
- You don't want users to have to change anything on their end.
- You're not going to need to make any firewall or infrastructure changes.
Preparation
Key to this strategy is having all the necessary files and other information ready for your rebuild. Here is a list of things to grab before you start. Make sure you've copied the files to your local system from the existing GMS server.
-
The name of your Trusted App from the GroupWise administration console.
- GroupWise Admin Console → System → Trusted Applications → Find the name of the one you use for Mobility and write it down.
-
Your Trusted App File.
From previous installations, you should have exported your
trusted app key to a text file and then used that when you
installed GMS before. You had to have this when you installed
GMS in the first place. On my server for example, I use
/opt/iso/mobility.txt. This could be any filename located anywhere on your existing GMS server, but you put it there so go find it. -
Your SSL certificate file.
This is located at
/var/lib/datasync/gms_mobility.pem. -
The latest GroupWise Mobility installation media.
For example,
groupwise-mobility-service-26.2-x86_64.iso. - Your network details, including IP address, subnet mask, gateway, DNS names, server name. Everything you need to rebuild the server and assign the correct info to it so it is functional on the network.
- Your VM configuration details: CPU Count, Memory, Disk Size Etc.
- Have all your users provisioned via GROUPS. This makes redeployment much faster. If you don't have them by groups currently, consider creating a Group in GroupWise, adding those same users to that group, and then using that Group on the new server to provision the users quickly.
-
Take screenshots of all your configuration screens
in the GroupWise Mobility Service dashboard. Every single
page. There are 5 total:
- General | GroupWise | Device | User Source | Single Sign-On
-
Multiple GMS administrators.
If you have multiple administrators that login to the GMS
dashboard for administration purposes, make sure to grab the
details of the configuration file so you can easily replicate
it on the new system. The file is here:
-
/etc/datasync/configengine/configengine.xml - The section you need is the top part in the header in the "GW" section. Each user should be defined in a separate "Username" tag.
-
Execution
This is a very high-level bullet pointed overview of how you get the new server built and in full production quick.
-
Shut Down the Old Server
Shut down the old server. It is imperative that the old server is not running.
-
Build the New SLES Server
Build new SLES 15 SP7 server from scratch. Configure it with the actual IP address, gateway, DNS etc. Register it and apply all updates so it is 100% fully patched. At this point you have a base server ready to go.
-
Copy the Required Files
Copy the files you grabbed from the old server and use WINSCP to get them to the new server. You'll need the following:
-
mobility.txt(or whatever your GroupWise Trusted App keyfile is). -
gms_mobility.pem(the SSL certificate, most likely your 3rd party SSL cert for your company). -
The GMS install ISO, for example
groupwise-mobility-service-26.2-x86_64.iso.
-
-
Configure the Firewall
Configure the firewall to allow the following ports to the GMS server: 443/tcp, 4500/tcp, 4500/udp, 8120/tcp.
Firewall commands:firewall-cmd --permanent --add-port=443/tcp firewall-cmd --permanent --add-port=8120/tcp firewall-cmd --permanent --add-port=4500/tcp firewall-cmd --permanent --add-port=4500/udp firewall-cmd --reload-
443/tcp: Connections from devices -
8120/tcp: Access to management console -
4500/tcp: Required for POA to notify GMS of messages -
4500/udp: Required for POA to notify GMS of messages
-
-
Install GroupWise Mobility Service
Mount the GMS ISO file and run through the installer and complete the GMS installation. You mount and run it via the following commands:
mount -o loop groupwise-mobility-service-26.2-x86_64.iso /mnt
cd /mnt
./install.sh
Step through it. Note the following:
- When prompted about if you want to use a self-signed cert, say Yes. We'll replace that later but this will get you through the installer for now.
- There will be a point where it asks you for the file with the Trusted App key. You'll need to know where it's at so you can load it at this step.
-
Configure the New GMS Server
Once the installer completes successfully, login to the GMS dashboard at https://x.x.x.x:8120.
DO NOT ADD ANY USERS OR GROUPS YET. That will just slow you down. You do that last. We have some other work to do first.
-
At the Linux console, copy the SSL certificate from
the old server. It should go here:
-
/var/lib/datasync/gms_mobility.pem - Don't mess with any of the other cert files in that folder.
-
- Go to the dashboard and configure all the settings to match what your old server used. You should have taken screenshots of the 5 config pages for reference.
-
If you have multiple administrators, edit the config
file that manages that aspect and paste in the
directives from your old server.
-
/etc/datasync/configengine/configengine.xml
-
-
Once all the settings match, reboot the server
for good measure.
- Make sure the GMS services start correctly at the Linux console.
- Make sure the services are running in the Dashboard.
- Resolve any errors or conditions. But it should be working at this point.
- Check in your browser to the Dashboard and make sure the correct certificate is loading. It should be using your 3rd party cert, not a self-signed cert.
- Go make any performance tweaks that you had before. Specifically, the Linux IO scheduler, "noatime" on the mounted partition, and the Linux swappiness. Refer to the "Misc. Performance Tuning" section of this document.
- Go to the Users tab and add the Groups in that contain the GMS users you need to provision. If you're using users instead of groups, do that here as well, but it's more tedious and time consuming.
- Once you see user accounts being added in the Dashboard, you're essentially done. Let GMS continue provisioning the users and synchronizing their data. As provisioning completes, users should be able to reconnect with their existing devices without making any changes. In my experience, approximately 98-99% of devices reconnect without intervention. A small percentage, typically 1-2%, may require the user to remove and re-add their account on the device. This is generally manageable and doesn't require any changes to the GMS server.
-
At the Linux console, copy the SSL certificate from
the old server. It should go here:
YES but our system is HUGE and it will take FOREVER
On larger systems, reprovisioning hundreds of users and their devices can take considerable time. I've worked with GMS environments supporting 500 or more users and even more devices. The rebuild procedure itself is essentially the same regardless of system size. What changes is how long the initial synchronization takes. This is why the procedure I've outlined deliberately leaves user provisioning until the very end. By that point, the server is built, GMS is installed, certificates are configured, and everything else is ready to go.
Once you start provisioning users, you're essentially finished with the rebuild. Walk away and let GMS do its work. Schedule this for an evening or weekend, particularly on larger systems, and give it time to process the initial synchronization. As users and devices reconnect, GMS may develop a backlog while it processes mail and other synchronization data. How long this takes depends on the number of users and devices, the volume of data, and how much historical mail you've configured GMS to synchronize. Don't mistake a busy system working through its initial synchronization backlog for a system that isn't functioning. Monitor its progress, but give it time to catch up.